
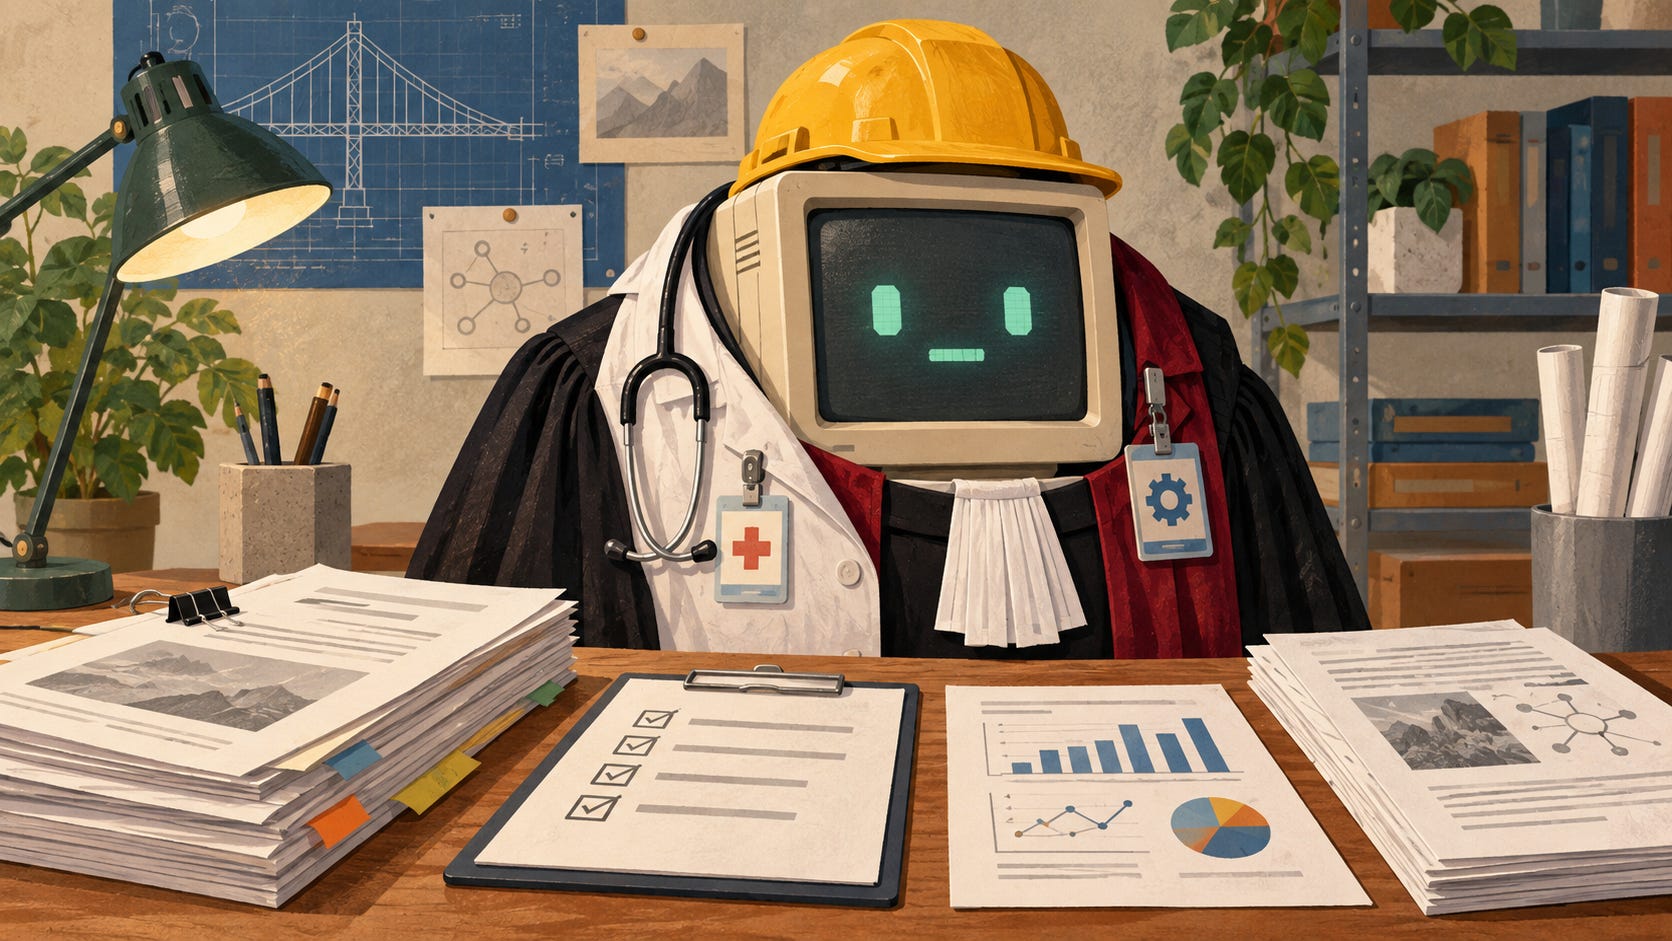
Prompt engineering contains a small corporate ritual that has survived an impressive number of model generations: before asking the model to do anything, promote it.
You are a world-class lawyer. You are a senior principal software architect. You are an elite McKinsey strategist with twenty years of experience in distributed systems, paediatric cardiology and, apparently, whatever else is in the next paragraph.
The model has no medical licence, no bar membership, no production pager, and no scar tissue from the migration that went wrong at 2:17 a.m. But congratulations. It has been promoted.
I think of this as cosplay prompting: giving the model an impressive identity and hoping the costume improves the work.
There is now a counter-claim floating around prompt-engineering discussions: this used to work, but modern models are too capable for it. Just ask directly. The cape is obsolete.
That correction is useful, but it is still too neat. The research does not show a clean moment when persona prompting expired. It shows something more annoying: the effect depends on the task, the model, the exact wording, the baseline, and what you measure. Expert labels are not a dependable accuracy upgrade. Roles can still change behaviour, and sometimes performance. Those are different claims.
The practical rule is simpler than the debate: give the model a job, not a résumé.
The prompt did not install a career
The phrase “role prompting” bundles together several things that should never have been treated as one technique.
Credential cosplay — “You are a world-class tax lawyer.”
Functional responsibility — “Review this contract for termination, liability and renewal risk.”
Audience framing — “Explain this to a CFO who understands finance but not distributed systems.”
Behavioural protocol — “Separate verified facts from assumptions; cite evidence; flag uncertainty.”
Simulation — “Respond as a buyer evaluating this onboarding flow.”
Only the first one claims, implicitly, that an identity label should make the model more knowledgeable or accurate. The others specify what work to do, what perspective to use, or how to communicate it.
That distinction matters because a model cannot acquire new domain knowledge from a flattering sentence about itself. A role prompt can change which patterns it samples, which concepts it foregrounds, how much jargon it uses, what risks it notices, or how it structures an answer. That can be useful. It is not the same as installing ten years of professional judgment with one line of text.
Current vendor guidance is actually more nuanced than the folklore. OpenAI still discusses role and identity guidance, but also tells developers to treat prompts as code, pin model versions and run evaluations because behaviour can change between model snapshots. Anthropic still recommends giving Claude a role, alongside clear instructions, context and examples. Google still lists persona or role as one optional component of a prompt, next to the actual task, constraints, context and output format.[7][8][9]
In other words, the vendors have not declared role prompting dead. They have quietly put it back where it belongs: one control among several. The industry then did what it often does with a nuanced control surface and turned one knob into a religion.
Why the costume got a reputation
It is worth remembering that role-play prompting did produce striking results in earlier research. This was not invented entirely by people selling prompt templates on social media.
A 2024 NAACL paper by Aobo Kong and colleagues tested a strategically designed role-play prompting method across twelve reasoning benchmarks. On ChatGPT, accuracy on AQuA rose from 53.5% to 63.8%. On the Last Letter task it jumped from 23.8% to 84.2%. The authors also found their role-play setup could act as a stronger trigger for chain-of-thought-style reasoning than a standard zero-shot baseline.[1]
Those are not rounding errors. If you saw results like that, you would reasonably conclude that role framing could matter.
But notice what the result does not establish. It does not establish that attaching prestige to any arbitrary task makes any future model smarter. It shows that a particular role-play intervention, on particular models and benchmarks, changed the model’s reasoning behaviour enough to improve results.
This is where prompt advice tends to go through its familiar laundering process. A paper finds a conditional effect. A blog turns it into a technique. A slide turns the technique into “best practice.” Six months later somebody is beginning a CSV-cleaning prompt with “You are the world’s foremost data scientist.”
Which would be harmless, except teams then confuse the costume with the mechanism.
Then the results stopped behaving
A different 2024 study gives the opposite impression. Mingqian Zheng and colleagues tested 162 personas across four model families and 2,410 factual questions. Adding personas did not improve performance overall compared with no persona. Gender, role type and domain could change results, but the effect was inconsistent. The researchers could identify personas that worked better for individual questions after the fact; reliably choosing the best persona in advance was much harder, with automatic strategies often doing no better than random selection.[2]
That is a fairly devastating result for “always start with an expert role.” A prompt trick that only works once you already know which costume wins is not much of a production strategy.
Then the 2025 EMNLP paper Principled Personas made the picture messier again. It evaluated nine state-of-the-art open models over 27 tasks. Expert personas usually caused positive or statistically non-significant changes, and Llama 3.1 70B with dynamic focused-expert personas showed strict improvement on 37% of tasks. But the same study found models surprisingly sensitive to irrelevant persona details, with drops of almost 30 percentage points in some settings.[3]
Read that carefully. “Personas do nothing” is wrong. “Personas reliably help” is also wrong. Sometimes an expert frame helps. Sometimes adding irrelevant decoration damages the result. The model is steerable, but not in the tidy way a prompt cheat sheet would like.
A 2025 Wharton Generative AI Labs report pushed specifically on the prestige claim. Six models were tested on GPQA Diamond and an MMLU-Pro subset using in-domain experts, mismatched experts and deliberately low-knowledge personas. Expert personas did not consistently improve factual accuracy; Gemini 2.0 Flash on MMLU-Pro was the notable exception. Low-knowledge personas were generally harmful, and mismatched roles could also degrade behaviour.[4]
The serious point underneath the comedy is that persona text can move the model. The problem is that “it moved” is not the same as “it got better.”
“Works” is doing far too much work
A lot of the argument disappears once you ask what “works” means.
If the metric is factual accuracy, “You are an expert” has weak support as a general technique. If the metric is tone, terminology, depth, perspective, empathy, critique style or audience fit, a role can be doing exactly what you want even when accuracy stays flat.
A 2026 preprint makes this distinction unusually visible. Across 1,140 open-ended questions, 38 expert roles and six domains, the authors found only small aggregate differences between persona conditions. But underneath the average, role prompting tended to increase perceived expertise depth while reducing clarity. The persona was not simply adding quality. It was trading one quality dimension for another.[6]
That sounds obvious once stated. Ask a model to sound like a specialist and it may produce more specialist language. Congratulations: the cardiologist costume came with cardiologist prose. Whether the reader needed cardiologist prose is a separate product decision.
Persona prompting is even more clearly a different problem when the persona is meant to simulate people rather than expertise. An EACL 2026 study found demographic persona prompting could improve classification on a highly subjective hate-speech task while degrading rationale quality; the simulated personas also failed to align reliably with the corresponding real demographic groups.[5]
So “respond as a 55-year-old nurse from X” should not be treated as cheap user research. A model can produce a plausible character. Plausibility is not representation. This is the same trap in a different costume.
There is no proven expiration date
The tempting modern story is that cosplay prompting worked on older, weaker models and stopped working on newer reasoning models.
I would not make that claim from the evidence we have.
The studies above are not a clean longitudinal experiment where the same prompt intervention, task set and evaluation are run across model generations until the effect vanishes. They use different models, different persona constructions, different benchmarks and different metrics. The sensible conclusion is not “role prompting died in 2025.” It is that there was never a universal role-prompting law to begin with.
Modern models do change the economics. OpenAI’s current guidance for reasoning models explicitly recommends straightforward prompts and warns that older incantations such as asking the model to “think step by step” may be unnecessary or counterproductive.[10] That should make us suspicious of any ritual text we keep copying forward merely because it once helped a different model.
But “less necessary” and “invalid” are not the same thing. If a current model already understands the task, a vague expert title may add little. If the role compresses useful information about responsibility, audience or decision criteria, it can still steer the answer in a useful direction.
The real change is that prompt engineering is becoming less like spell casting and more like software configuration. Specify the behaviour you need. Test it against a baseline. Keep it only if the measured outcome improves.
Preference is not performance. Tradition is definitely not performance.
A code review without the cape
Suppose a team wants an AI coding agent to review a legacy payment-handler change before merge.
The cosplay version looks familiar: “You are a world-class principal engineer and payments expert with twenty years of experience in distributed systems and security. Perform an expert review.”
It may produce a good review. It may also produce a very confident essay about dependency injection. The prompt has told the model how impressive it is, but very little about what would make this review useful.
Now remove the biography and give it a job.
“You are the merge-gate reviewer for this payment change. Decide whether it is safe to merge. Check duplicate-charge risk, idempotency, transaction boundaries, retries, concurrency, authorization, secret handling, rollback behaviour and missing tests. For every issue, cite the code evidence and explain the concrete failure mode. Separate confirmed defects from hypotheses. Do not propose refactors unless they address a demonstrated risk. Finish with Block, Warn or Pass and the reasons.”
The second prompt still contains a role. But the role is operational. It defines responsibility, scope, evidence, uncertainty handling and the decision to produce.
Imagine the model spots that a retry path can call the charge operation twice unless an idempotency key is stable. Useful. It then claims the ORM automatically rolls back a nested transaction in a way that sounds plausible but is wrong for the version you run. Also normal.
The verification step is not “ask the model if it is sure.” You check the transaction implementation, the ORM documentation and the tests. If the risk matters, you reproduce it. A title is not a unit test.
This is the operating lesson: use prompting to focus judgment, not to manufacture authority. The model can help widen the search, structure the review and surface hypotheses. Evidence still decides whether the hypothesis survives.
In practice, this is also easier to evaluate. You can run the same patch through the cosplay prompt and the operational prompt, then compare defect recall, false positives, citation quality and review time. Now you are doing engineering rather than prompt astrology.
Where roles still earn their costume
I would still use roles. I would just stop expecting the role name itself to carry the system.
Roles are useful when they compress a real behavioural contract. “Security reviewer” can mean prioritize exploitability and trust boundaries. “Editor for a technical audience” can mean preserve technical detail while cutting repetition. “Product manager preparing a launch review” can mean surface dependencies, unresolved decisions and measurement gaps. The useful content is the implied work pattern; when it matters, make that pattern explicit.
Roles are also useful when the goal is genuinely perspectival. Asking for a skeptical reviewer, an impatient first-time user, or a regulator’s likely line of questioning can help generate attack angles you might not have considered. That is ideation, not evidence. The output becomes a queue of things to verify, not a synthetic substitute for the people being simulated.
And if your only goal is tone, cosplay is fine. Tell the model to write like a patient tutor, a terse incident commander, or a mildly annoyed staff engineer. Style is exactly the thing a style instruction is allowed to change.
What I would not do is use “You are an expert” as the control that is supposed to make a high-stakes answer correct. For correctness, give the model better context, access to authoritative sources, tools, examples, constraints and a verification path. Then evaluate the result on the task you actually care about.
If the expert label survives that evaluation, keep it. If removing it changes nothing, delete it. If it makes the model sound more authoritative while accuracy stays flat, delete it faster.
The annoying question
So, is cosplay prompting still valid?
Yes, as steering. No, as a general intelligence upgrade.
There is no solid evidence that modern models crossed some threshold after which roles stopped mattering. There is strong evidence that expert-persona effects are conditional, sometimes negligible, sometimes positive, sometimes harmful, and easy to confuse with changes in style or depth.
The useful question is not “Should I tell the model it is an expert?” It is “What behaviour am I trying to cause, and can I specify and measure that behaviour directly?”
If “You are a world-class engineer” is shorthand for a review process you have tested and it improves outcomes, fine. Keep the cape.
If it is there because somebody copied a prompt from 2023 and nobody wants to touch the sacred paragraph, that is not prompt engineering. That is a ritual with better formatting.
Give the model the responsibility, the evidence, the constraints and the test. Let the résumé stay fictional.
Notes and References
1. Aobo Kong, Shiwan Zhao, Hao Chen, Qicheng Li, Yong Qin, Ruiqi Sun, Xin Zhou, Enzhi Wang, Xiaohang Dong, Better Zero-Shot Reasoning with Role-Play Prompting, NAACL / Association for Computational Linguistics, 2024. Used for the twelve-benchmark role-play study and the reported AQuA and Last Letter accuracy changes.
2. Mingqian Zheng, Jiaxin Pei, Lajanugen Logeswaran, Moontae Lee, David Jurgens, When “A Helpful Assistant” Is Not Really Helpful: Personas in System Prompts Do Not Improve Performances of Large Language Models, Findings of EMNLP / Association for Computational Linguistics, 2024. Used for the 162-persona, four-model-family, 2,410-question evaluation and the difficulty of selecting a reliably beneficial persona.
3. Pedro Henrique Luz de Araujo, Paul Röttger, Dirk Hovy, Benjamin Roth, Principled Personas: Defining and Measuring the Intended Effects of Persona Prompting on Task Performance, EMNLP / Association for Computational Linguistics, 2025. Used for the nine-model, 27-task evaluation, the 37% strict-improvement result for focused dynamic experts on Llama 3.1 70B, and sensitivity to irrelevant persona attributes.
4. Savir Basil, Ina Shapiro, Dan Shapiro, Ethan Mollick, Lilach Mollick, Lennart Meincke, Prompting Science Report 4: Playing Pretend: Expert Personas Don’t Improve Factual Accuracy, Wharton Generative AI Labs, 2025. The report was revised in 2026; the underlying study is dated December 2025. Used for the six-model GPQA Diamond and MMLU-Pro experiments showing no consistent factual-accuracy gain from expert personas and generally harmful effects from low-knowledge personas.
5. Jing Yang, Moritz Hechtbauer, Elisabeth Khalilov, Evelyn Luise Brinkmann, Vera Schmitt, Nils Feldhus, Persona Prompting as a Lens on LLM Social Reasoning, EACL / Association for Computational Linguistics, 2026. Used for the finding that persona prompting could improve classification on a subjective hate-speech task while degrading rationale quality and failing to reproduce real demographic alignment.
6. Shuai Xiao, Su Liu, Weikai Zhou, Jialun Wu, Xinjie He, Zhiyuan Lin, Qiyang Xie, When Does Persona Prompting Actually Help? A Retrieval and Metric Analysis of Expert Role Injection in LLMs, arXiv preprint, 2026. Preprint; not treated here as peer-reviewed evidence. Used for the 1,140-question analysis suggesting a trade-off between expertise depth and clarity rather than a broad aggregate quality gain.
7. OpenAI, Prompt engineering, OpenAI API documentation, 2026. Used for current guidance on role/identity instructions, model-specific prompting, snapshot variability, prompt versioning and evaluation.
8. Anthropic, Prompting best practices, Claude Platform documentation, 2026. Used for current guidance to use clear and direct instructions, examples and system-role framing where it helps focus behaviour and tone.
9. Google Cloud, Overview of prompting strategies, Vertex AI documentation, 2025–2026. Used for the framing of persona/role as one optional prompt component alongside task, constraints, context, examples and output format.
10. OpenAI, Reasoning best practices, OpenAI API documentation, 2026. Used for the current recommendation that reasoning models generally perform best with straightforward prompts and that explicit chain-of-thought requests such as “think step by step” may be unnecessary or counterproductive.