
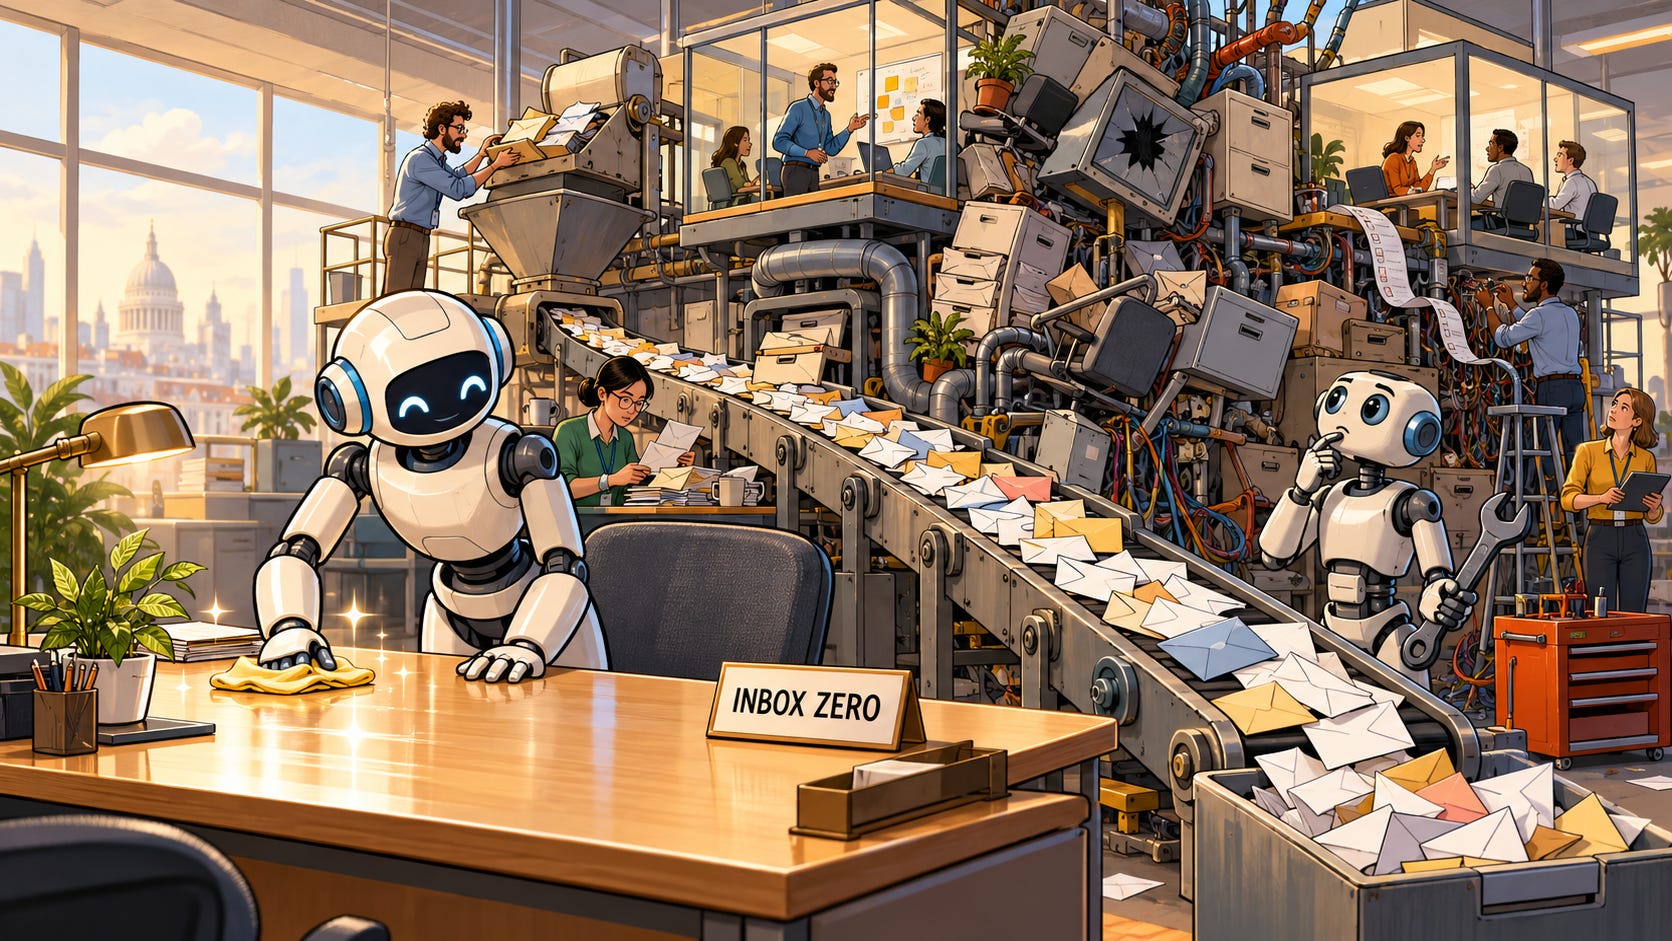
An empty inbox is a beautiful thing. So is an airport baggage carousel before the bags arrive. Neither tells you very much about what is currently being loaded onto the plane.
The appeal is obvious. A crowded screen becomes a clean screen. A number goes down. Something that was demanding attention stops demanding it, at least in that particular rectangle.
My version of this started with a task app. Today could look empty while categorised, unscheduled tasks existed elsewhere. Inbox was no substitute for seeing them: giving a task a category could remove it from that view without deciding when to do it.
The tasks had acquired accommodation. They had not necessarily acquired a plan.
Griply’s documented rules make this understandable. Its Inbox is for tasks without a goal or life-area link, planned date or deadline. It also provides All Tasks, filters and Smart Lists for broader review. A focused daily screen has a perfectly reasonable job. But in my experience, its reassuring emptiness can feel as though nothing is happening while work waits elsewhere.[1]
Lunatask makes the contrast visible for me. In the setup I use, today’s plan sits alongside what is coming and what is waiting for later. I can bring a future task into today or tomorrow while keeping the wider list in sight. Its Plan Your Days workflow supports that broader planning horizon. The difference is what stays in front of me as I plan, rather than what I remember to go looking for.[1]
For me, Lunatask makes more sense from the human side of the screen. But as I move towards working with a personal AI assistant, I also need that assistant to be able to use the system. If it cannot reliably access my tasks and help with the changes I authorise, the better interface loses its point for the way I want to work. I would still be the person carrying information between the two. Safe, reliable access, with clear limits on what the assistant may change, becomes part of what makes a task app useful.
A wider view is a better answer to “What am I carrying?” Seeing the future work gives me something to choose from. Moving it into today gives it a place in the plan. Neither step, by itself, stops the next avoidable task from arriving.
That little distinction scales surprisingly well.
We can organise work, move it, summarise it, schedule it and sometimes genuinely finish it. Yet the arrangements generating tomorrow’s avoidable work can continue in excellent health.
Now we are giving those arrangements AI.
This could be enormously useful. It could also produce the world’s most efficient department for dealing with consequences. The department will have agents, integrations and a weekly chart showing that consequences are being handled 23 different ways. Nobody will have asked why the same consequence keeps turning up wearing a new ticket number.
The interesting question is what we want the machine to optimise. A shorter queue? A solved problem? Less effort across everyone involved? Fewer unnecessary problems next week?
Those outcomes can overlap. They can also disagree violently while sharing a dashboard.
The loading bay is not the whole business
Imagine a company whose loading bay receives a parcel every time somebody needs something. Some parcels contain valuable orders. Some contain urgent problems. Some contain useful questions that prevent expensive mistakes.
Others arrive because the delivery status is invisible, the instructions contradict the form, or nobody knows who can approve a routine decision.
A productivity system can label the parcels, stack them neatly and arrange them by urgency. An assistant can open them and do the enclosed work. Both are valuable services.
But if a broken process sends the same parcel back every Tuesday, making Tuesday’s handling faster leaves an interesting opportunity unexamined.
Perhaps the process can be fixed. Perhaps fixing it costs more than dealing with the occasional parcel. The useful move is to investigate, rather than assuming the arrival stream is an immutable feature of the universe, like gravity or a meeting that has outlived its organiser.
It helps to separate a few quantities that ordinary productivity language bundles together.
Messages are not identical to requests. One email can contain several jobs. Ten emails can concern one job. A message may prevent work by answering a question before somebody builds the wrong thing.
Interruptions are different again. A digest can reduce interruptions while containing exactly the same obligations. Moving email into chat can change the notification sound without improving the situation.
And visible backlog is merely the work shown in the chosen view. Archiving an email may be good processing. If the obligation still exists, the archive button has not completed it.
This is ordinary accounting. Accepted work comes in; completed or legitimately cancelled work goes out. Transferring it may rebalance who can handle it. Hiding it changes the display.
A green dashboard can be perfectly accurate about the display.
First, acquit Merlin Mann
Before convening a tribunal for Inbox Zero, we should invite its inventor to the correct hearing.
Merlin Mann’s original approach already concerned limited attention, sensible processing, boundaries and the work worth accepting. His 2007 Google talk discussed preventing low-value commitments from entering the system. Emptying the inbox was part of the method; compulsively worshipping an empty inbox is a much thinner interpretation.[2]
So the argument here is with a reduced version of productivity: the idea that visible clearance is sufficient evidence that the workload is under control.
Mann was asking harder questions before the inbox acquired an AI subscription.
Processing itself also deserves a defence. Someone facing a frightening backlog may need a safe triage pass before undertaking organisational archaeology. Important deadlines and useful information are inside the pile. Small jobs can unblock other people. A quick completion may be exactly the right use of a tired half-hour.
Research offers a modest reason to watch the metric, rather than a licence to sneer at small tasks. In one experiment, people under higher cognitive load were more likely to choose an apparently easier task. It studied workload and task selection, not inbox gestures or neurotransmitters.[3]
We do not need to invent a dopamine laboratory inside the archive button. The visible satisfaction is enough for the argument: clearance is easy to notice; a future problem prevented may leave nothing to count.
That makes prevention awkward to demonstrate in a product demo. The screen recording consists of an employee doing something else because an unnecessary request never arrived. Marketing asks whether the absence could have a more exciting animation.
AI has at least four different jobs here
The phrase “AI handles your workload” covers several quite different promises. A useful evaluation starts by asking which one is actually being offered.
First, organise and protect attention.
Summarise the thread. Rank the tasks. Find time in the calendar. Batch the alerts. Reclaim, for example, documents scheduling and rescheduling existing commitments, focus protection and task-tool connections.[4]
This can remove genuine coordination work. A calendar that no longer requires twenty minutes of negotiations has delivered something worthwhile. The original meeting may still exist, and may still be unnecessary. Those are separate questions.
Second, execute accepted work.
Prepare the report, reconcile the records, make the authorised update. This can discharge an actual obligation. Calling it elaborate filing would be unfair to both the technology and anyone who has reconciled records.
Grok Bot is a useful illustration of the ambition. Its beta announcement describes always-on agents working across applications on a cloud computer. Vendor examples include CRM updates, operational work, bug reproduction and a debugging handoff. It also describes preparing outbound sales drafts.[5]
Those examples point in several directions. An agent might finish work for one person, help investigate a recurring fault, or prepare the next message for somebody else’s inbox. The announcement establishes the vendor’s intended capabilities. It does not establish net workload savings, reliable root-cause prevention, or why people adopt the product.
Delegating execution is a substantial step. Choosing which work ought to exist remains another step.
Third, resolve the need at intake.
A customer asks where an order is. A system consults reliable records and answers accurately. A colleague needs a routine service action; an authorised agent completes it without a human handoff.
The customer still had a need. Successful self-service reduces the human handling required to satisfy it. That is useful even if the same category of question remains common.
Fourth, prevent avoidable recurrence.
Why did the customer need to ask? Perhaps tracking information was missing. Perhaps the promised delivery date was unrealistic. Perhaps the product repeatedly failed in the same place.
An agent could group related cases, check whether they really share a cause, and propose a change. An authorised team could fix the underlying problem. Only then, with outcomes checked over time, could we say the preventive work had succeeded.
A recommendation to fix something is still a recommendation. It can be beautifully formatted and remain entirely unimplemented. Organisations had this technology long before artificial intelligence.
These four jobs can support each other. Better handling can reveal patterns. A good answer can expose a documentation gap. Improved documentation can prevent later questions.
But we should be able to tell which kind of progress occurred. Otherwise “handled” becomes an exceptionally versatile word, capable of describing everything from a repaired defect to a customer who went away.
The time savings are real enough to take seriously
There is evidence that helping people process existing work saves time. Any argument that dismisses this as fake productivity has thrown away useful evidence to protect a joke.
A randomised field experiment involving 7,137 workers at 66 large firms examined access to Microsoft 365 Copilot. Its main analysis found an average reduction of about 1.4 hours a week in Outlook activity among workers assigned access, with a modest reduction in after-hours digital activity. It found no significant average change in meeting time or the measured quantity and composition of tasks.[6]
That is a real benefit within the study’s scope. The researchers did not observe work content or directly measure performance quality. The participants were selected, Office-heavy workers at large early-adopting firms. It is evidence worth using, with those boundaries attached.
A separate study of AI assistance for 5,172 customer-support agents found roughly 15% more issues resolved per hour on average. Effects varied across workers, and the main deployment was observational rather than a giant randomised trial.[7]
Again, helping someone resolve legitimate incoming needs faster is useful. It does not require the needs themselves to disappear.
The evidence reviewed for this article does not establish that upstream AI prevention generally beats downstream assistance. There is no honest basis for replacing “summarise everything” with “redesign everything” and announcing that science has completed the procurement process.
Prevention has setup and maintenance costs. A rare question may be cheaper to answer than to eliminate. Some recurring needs are simply part of serving people.
The more interesting ambition is to make the choice visible: handle this efficiently, or invest in changing why it keeps happening?
Sometimes the answer will be both. Sometimes the heroic transformation programme should be cancelled in favour of a useful two-sentence reply.
The queue can go quiet for several reasons
Intercom’s Fin provides a helpful example of why definitions matter. Its documentation distinguishes confirmed resolutions from assumed resolutions when a customer leaves without requesting a teammate or giving negative feedback. Its broader deflection measure can also include people leaving before an answer or after negative feedback.[8]
These are disclosed operational definitions. They are not evidence that the company is deceiving anyone, nor that every assumed resolution failed.
They do mean that fewer conversations reaching a human cannot, by itself, tell us how many needs were successfully met.
A customer might have received a useful answer. They might have worked it out independently. They might have abandoned the attempt. Follow-up sampling, repeat contacts and actual service outcomes can help distinguish those possibilities.
Silence is excellent at concealing its reasons.
Fin also analyses unsuccessful conversations and recommends improvements to content, data access and available actions. It offers escalation controls and human approval steps. Those features complicate any sweeping claim that existing products never look beyond queue processing.[9]
Still, improving the answer to “Why did this break again?” and making it break less often are distinguishable achievements.
The same care applies internally. An agent can turn a request into a polished report, then require three colleagues to check it. If that review is necessary and worthwhile, good. If the report should never have been commissioned, the organisation has automated the first stage of a larger inconvenience.
AI can also make outbound work cheaper to create. The hypothetical sender saves five minutes; recipients spend twenty checking the result. Those invented numbers are an illustration, but the accounting question is real: whose effort appears in the savings calculation?
A system that saves me time by consuming yours may still receive an enthusiastic testimonial from me.
Give the agent a recurring problem
Consider a hypothetical small software business receiving repeated questions about the same export failure.
The first AI workflow drafts replies more quickly. The second walks customers through a reliable workaround. Both may improve service immediately.
A third workflow examines the repeated cases. Are they actually the same error? Do they affect a particular file type, account setting or sequence of actions? Is the apparent pattern merely the most common label agents select when hurried?
This is where an assistant can earn its keep before anyone gives it authority to change production. It can assemble evidence, identify uncertainty and propose a bounded investigation.
Perhaps the error message omits the permitted file format. Perhaps onboarding gives the wrong instructions. Perhaps the export itself needs repair. The relevant owner can approve and implement a fix, then check whether customers succeed more often.
The bot may eventually have fewer opportunities to demonstrate its excellent apology.
This approach extends beyond software defects. Repeated status requests may reveal an unreliable status source. Repeated clarification may reveal a request form that never asks what decision is needed. Repeated approval traffic may reveal unclear decision rights.
There is adjacent evidence that workflow redesign can reduce unnecessary circulation. One internal-medicine clinic introduced clearer routing, responsibility standards and dedicated staffing time. A non-randomised comparison found a greater reduction in messages per physician clinical full-time equivalent than in comparison clinics.[10]
That does not prove fewer patient needs, better clinical outcomes or equivalent benefits in an office. Several changes occurred together. It does show that investigating the communication process is a practical intervention, rather than an entirely new idea waiting for an agent-shaped logo.
The limits matter. An assistant cannot promote itself to policy owner because an approval chain looks repetitive. A worker who cannot change the process should not receive a lecture about taking ownership of the arrival rate.
Sometimes the useful output is evidence for the person with authority to act. Sometimes it is better triage within the constraints. Sometimes the organisation needs more capacity.
“Please become more disciplined” is a remarkably cheap staffing plan.
Measure the whole journey
For a team wanting to test this, start with one recurring category of work. Choose something narrow enough to investigate, with an identifiable owner and outcomes people actually care about.
Count the underlying needs as well as the messages. Record repeat contacts, time spent across requesters and handlers, successful outcomes, unresolved cases and work shifted into other channels. Include setup, review, exception handling and maintenance.
Then compare sensible alternatives where feasible: assist the current handling; resolve more needs at intake; or make an authorised change intended to prevent recurrence. A staggered rollout or concurrent comparison gives a stronger basis than declaring victory after a quiet week.
Allow the experiment to produce an inconvenient answer. Faster handling might provide the same service more cheaply than redesign. The preventive change might create a cumbersome form that saves the recipient two minutes by giving every requester ten minutes of homework.
That would be bureaucracy with a favourable local measurement.
Measure recurrence against relevant activity. If the business gains customers, raw support volume may rise while problems per customer fall. More contact can reflect growth, trust or better access. A complaint that finally reaches the right person is not a productivity failure.
Keep consequential failures separate from average speed. A system that handles routine requests quickly while losing the occasional urgent case needs more than a reassuring mean. Preserve human escalation, access for people who cannot self-serve, and a route to reverse a harmful change.
The desired result is equivalent or better outcomes with less avoidable total effort. An emptier queue is one possible symptom.
For personal work, the smaller version is enough. Use the daily view to do today’s work. Keep a dependable way to review commitments outside it. When the same avoidable chore returns, ask whether there is one reasonable change that would stop its next appearance.
There is no need to build a personal operations centre to avoid two emails. The operations centre will want a weekly review.
The best automation may have less to show
A task manager can help us see work. An assistant can help us do it. A service agent can meet a need before it becomes another person’s interruption.
We should keep those gains.
We can also ask the system to help examine the machinery producing avoidable work: the repeated fault, the missing information, the unclear owner, the unnecessary commitment, the notification nobody can act on.
Some machinery will justify repair. Some will be cheaper to live with. Some apparent nuisance will turn out to be a legitimate need we had failed to understand.
That is a more demanding brief than “make the number smaller”. It requires evidence, authority, judgement and a willingness to count effort outside our own screen.
It also offers a less theatrical kind of success. No triumphant archive animation. No record number of tickets processed. Just a problem that happens less often, while people still get what they need.
The loading bay is clean. Excellent.
Now let the robot walk over and ask why the factory keeps sending back the same parcel.
Notes and references
1. Griply, “Inbox”, “Filters”, “Smart Lists” and “View All Tasks in One Place”; Lunatask, “Workflows” and “Today Calendar”. These document the available review and planning views. The comparison describes my own setup and experience, not an absence of broader views in Griply or evidence that either app reduces incoming work.
https://griply.app/help/features/inbox
https://griply.app/help/features/filters
https://griply.app/help/features/smart-lists
https://griply.app/changelog/all-tasks
https://lunatask.app/docs/features/tasks/workflows
https://lunatask.app/docs/features/calendar
2. Merlin Mann, “Inbox Zero”, Google TechTalks, 2007. Historical discussion of processing, attention, boundaries and commitments. No direct quotation from the talk is used here.
3. KC, Staats, Kouchaki and Gino, “Task Selection and Workload: A Focus on Completing Easy Tasks Hurts Performance”, Management Science, 2020. The article draws narrowly on the experimental task-choice finding; it does not attribute a neurological mechanism to inbox behaviour.
https://pubsonline.informs.org/doi/abs/10.1287/mnsc.2019.3419
4. Reclaim, “Getting started with Reclaim” and “Reclaim 2.0 FAQ”. Product documentation, rather than an independent evaluation of net workload reduction.
https://help.reclaim.ai/en/articles/14846468-getting-started-with-reclaim
https://help.reclaim.ai/en/articles/15280604-reclaim-2-0-faq
5. xAI, “Introducing Grok Bot”, 11 August 2026. Vendor announcement and examples; not a controlled evaluation of reliability, adoption causes or net workload savings.
https://x.ai/news/introducing-grok-bot
6. Dillon, Jaffe, Immorlica and Stanton, “Shifting Work Patterns with Generative AI”, November 2025 version. The 1.4-hour weekly Outlook reduction is the intention-to-treat estimate for assignment to access, rather than the larger instrumental-variable estimate for use. The study did not directly observe content or performance quality.
https://arxiv.org/pdf/2504.11436
https://www.microsoft.com/en-us/research/publication/shifting-work-patterns-with-generative-ai/
7. Brynjolfsson, Li and Raymond, “Generative AI at Work”, Quarterly Journal of Economics, 2025. Staggered deployment and quasi-experimental analysis at one support organisation; the full 5,172-agent deployment was not a randomised controlled trial.
https://academic.oup.com/qje/article/140/2/889/7990658
8. Intercom, “Reporting metrics & attributes” and “Fin AI Agent reporting”. Definitions of confirmed and assumed resolution, and broader deflection measures. Disclosed measurement definitions do not establish whether an individual customer succeeded or abandoned an attempt.
https://www.intercom.com/help/en/articles/7022438-reporting-metrics-attributes
https://www.intercom.com/help/en/articles/7837533-fin-ai-agent-reporting
9. Intercom, Fin recommendations, escalation guidance and human-in-the-loop procedure approvals. Product documentation shows existing improvement and escalation mechanisms; it does not establish root-cause prevention of customers’ original problems.
https://www.intercom.com/help/en/articles/11390088-optimize-fin-instantly-with-the-help-of-ai
https://www.intercom.com/help/en/articles/14468561-human-in-the-loop-approvals-for-fin-procedures
10. Hadeed and colleagues, Journal of General Internal Medicine, 2025, clinic inbox workflow study. Non-randomised comparison combining routing guidance, standards and staffing time; reduced messages per physician clinical full-time equivalent do not establish reduced patient need or improved clinical outcomes.