
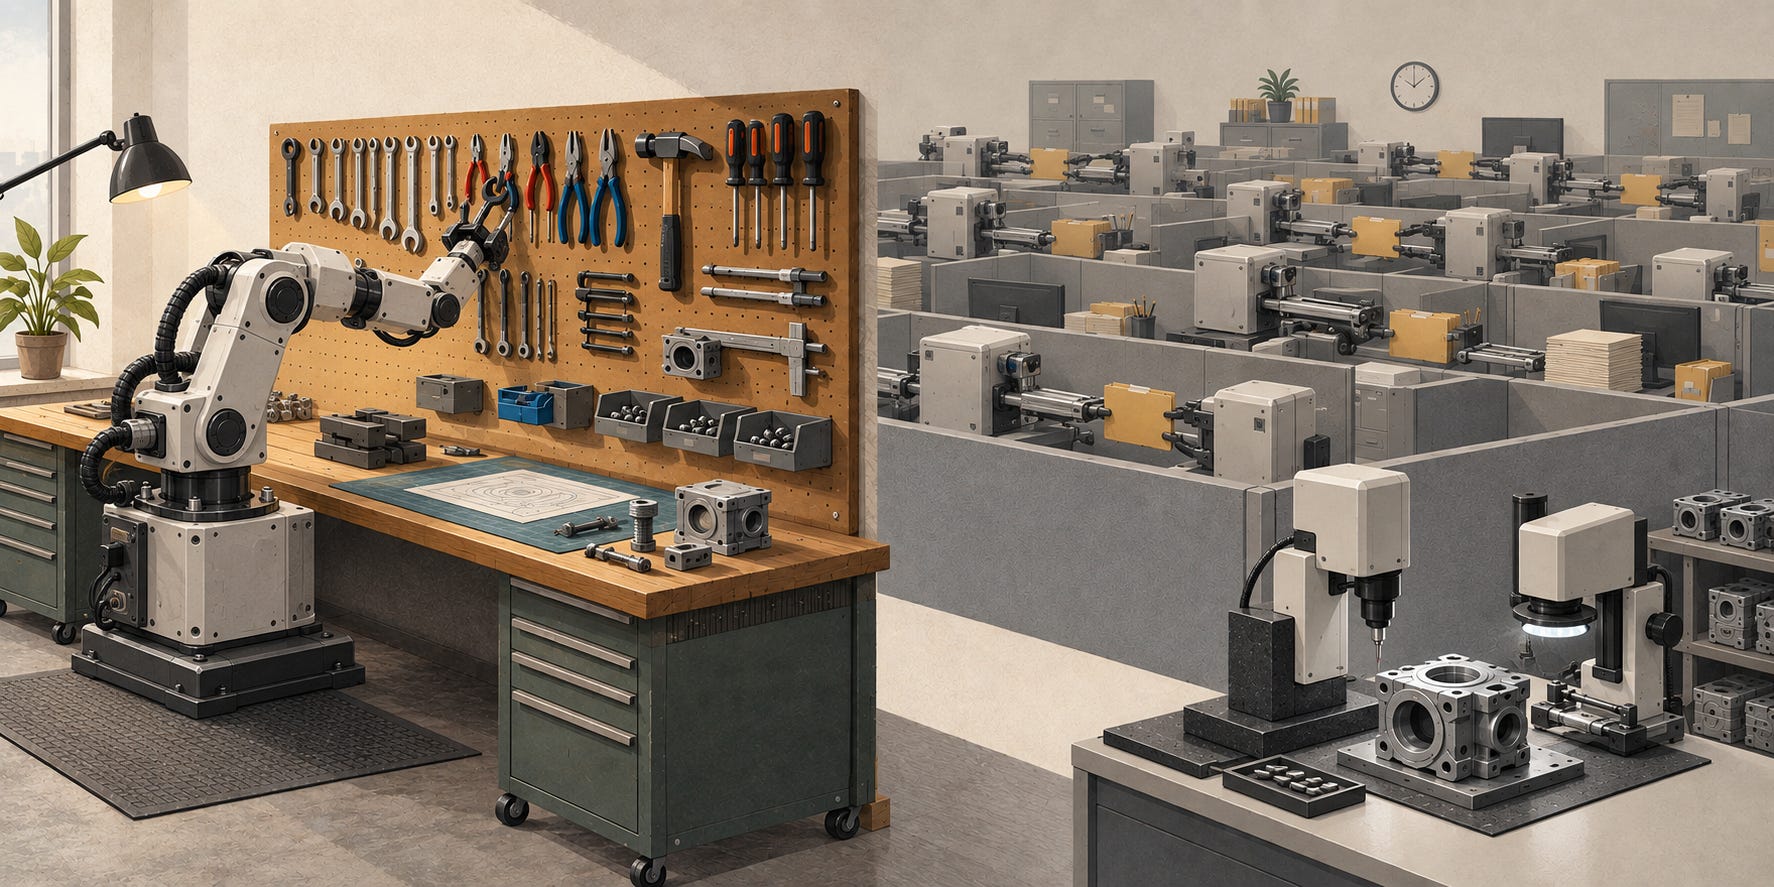
Imagine asking an AI system to fix a bug and discovering that it has first appointed a product manager, an architect, a backend engineer, a tester, and someone whose main contribution is summarizing what the other four said.
The bug is still there. But it now has stakeholders.
This is the version of the agent-team pitch I find least convincing: take a capable model, divide its work among several copies with impressive job titles, and assume the resulting organization must be smarter than the original.
Maybe. But a reporting line is not an optimization.
My starting hypothesis is that some elaborate agent teams preserve workarounds for limitations that newer models handle better: fragile long conversations, muddled instructions, weak planning, and difficulty carrying a task across stages. That does not make every team obsolete. It makes the old justification something to retest, not inherit.
For work that needs one coherent view of a problem, I would start with one capable agent, a well-maintained library of specialist skills, and explicit checks. I would add separate agents only when separation produces a measurable benefit.
One owner. Many skills. Selective delegation.
That is a design preference supported by the research below, not a universal benchmark result. The evidence does not establish that one modern agent always beats a team. It does give us good reasons to stop treating the team as the premium package.
A specialist is not a job title
We need to separate three things that the sales diagram likes to put in the same box.
A persona tells the model how to approach or present its work: act as an architect, be a skeptical reviewer, prioritize accessibility.
A skill supplies reusable knowledge about doing the work: the procedure, relevant examples, scripts, constraints, and checks.
A separate agent runs its own decision loop, with its own working context and whatever tools the system gives it. LangChain’s documentation explicitly distinguishes on-demand skills, where one agent remains in control, from subagents and handoffs. These are different design choices, not different spellings of specialization. [1]
My objection is not to the word “architect.” It is to treating that word as evidence that another execution boundary is necessary.
Suppose the same underlying model is given the title “senior database engineer.” If we have supplied no additional database knowledge, tools, procedures, or evidence, what precisely have we specialized?
We have certainly specialized the introduction.
Now consider a database-migration skill that explains the project’s migration conventions, identifies the schema source of truth, includes validation commands, and specifies what to check before proposing a destructive change. That supplies something the agent can actually use.
Anthropic describes Agent Skills as packages of instructions, scripts, and resources that general-purpose agents discover and load as needed. The design separates having access to expertise from loading all that expertise into every prompt. [2]
That is the abstraction I would usually invest in first. Put the hard-won procedure somewhere reusable. Test it. Improve it when it fails. Let either the main agent or a delegated worker use it.
There is no need to make expertise permanently belong to a fictional employee.
This also changes what a meaningful specialist would look like. A separately trained model, a domain-specific solver, an unusual data source, or a genuinely different tool environment may justify a separate component. A different name above the same capabilities is a much weaker case.
Specialization should describe what the system can do differently, not what it calls itself before doing the same thing.
Some of the scaffolding really can go away
The idea that agent architectures can outlive the limitations they were built around is not just a convenient insult.
In its March 2026 report on long-running application development, Anthropic described removing forced context resets after moving from Sonnet 4.5 to Opus 4.5. With Opus 4.6, it also removed the sprint structure previously used to organize the build. It retained the planner and evaluator where they still helped; on tasks within the stronger generator’s capabilities, evaluation could become unnecessary overhead. These were engineering experiments, not a universal comparison across all coding work. [3]
That is the interesting lesson: an architecture can contain both temporary scaffolding and useful structure. Improving the model does not necessarily remove both.
I would therefore treat every extra stage as a claim: without this stage, some identifiable failure becomes more likely.
Perhaps the agent forgets a requirement. Perhaps it starts coding before resolving an ambiguous interface. Perhaps it produces a plausible-looking screen whose main interaction does not work.
Those are testable problems. “We need a planning department” is a staffing decision wearing a lab coat.
If a planning skill and a required implementation plan solve the first problem, keep them. If a fresh-context planner reliably improves the scope, keep that instead. The point is to preserve the useful behavior, not the original cast.
But there is a trap in taking the argument too far. Better models can also become better at delegation, verification, and integrating other agents’ findings. Improvement does not logically guarantee that single-agent systems win more often forever.
My inference is narrower: the right boundary moves as capabilities change. A workflow justified by last year’s failure trace should face this year’s test suite.
The expensive mistake is not building scaffolding. It is turning scaffolding into a listed building.
A skill library is not a prompt landfill
“One agent with lots of skills” needs an important qualification.
I mean a large pool of available capabilities, not a single prompt containing every procedure the organization has ever written, including the printer troubleshooting guide and a deeply emotional document about branch naming.
The active context should contain what this task needs.
The June 2026 revision of SkillsBench evaluated 87 tasks across 18 model–harness configurations: combinations of a model and the software that runs it. Curated skills increased the average pass rate from 33.9% to 50.5%, a gain of 16.6 percentage points. Tasks with focused bundles of one to three skills showed larger gains than those with bigger bundles. That does not establish a universal three-skill limit: the groups contain different tasks. Nor is SkillsBench a direct comparison of one skilled agent against a team. [4]
What it supports is more modest and more useful: well-chosen procedural help can matter, and more material is not automatically better.
I would organize a skill library around a small discovery layer: what each skill is for, when to use it, and what output it produces. Load the relevant procedure when needed. Keep bulky references and executable utilities separate. That follows the progressive-disclosure model in Anthropic’s skills design. [2]
Then keep task state separate from both the skills and the conversation: current requirements, decisions, unresolved questions, changed artifacts, and verification results. Anthropic’s context-engineering guidance treats selective retrieval, compaction, and persistent notes as complementary ways to manage long work. [5]
In this design, “one owner” means continuity of responsibility for the task. It does not mean one immortal chat transcript, one model call, or a heroic refusal to clear irrelevant output.
There is also a real counterargument here. LangChain’s worked examples show that isolated subagents can process fewer total tokens on some multi-domain tasks than a single agent that accumulates all the domain instructions. Those examples illustrate the tradeoff; they are not universal production measurements. [1]
So I would measure the active context and the bill, rather than assume fewer agents always means fewer tokens.
A library should help you find the right book. It should not require you to swallow the building.
The task matters more than the team size
The strongest reason to distrust blanket claims is that the experimental results point in both directions.
The April 2026 revision of Towards a Science of Scaling Agent Systems compared 260 configurations across six benchmarks and five architectures. Relative to single-agent baselines, reported performance changes ranged from a gain of 80.8% on decomposable financial reasoning to a decline of 70.0% on sequential planning. The authors’ most robust finding was diminishing benefit from coordination as single-agent baselines became stronger. [6]
That is not “multi-agent works” or “multi-agent fails.” It is a warning about matching coordination to the work.
The study’s aggregate SWE-bench Verified results also favored the single-agent baseline, but that evaluation used only 20 instances per configuration, with wide uncertainty. It is not a verdict on every repository, modern model, or purpose-built coding team. [6]
Here is how I would translate the evidence into a working decision.
Can the subtasks make useful progress without repeatedly renegotiating the same assumptions?
If three investigations can each return an independent piece of evidence, parallel workers have a sensible job. If every next step depends on the evolving state of the previous one, splitting responsibility may mostly create more opportunities to misunderstand that state.
Consider a hypothetical chain: one agent interprets a requirement, another turns the interpretation into an interface, a third implements it, and a fourth tests the implementation against the interface. If the original interpretation was wrong, the chain can produce beautifully consistent evidence that it built the wrong thing.
The problem is not the number four. It is the absence of a check against the original requirement.
Equally, keeping everything with one agent does not make the first interpretation correct. It merely removes some translation boundaries. Verification still has to happen.
I would rather draw the dependencies first and decide the agent boundaries afterward.
The org chart is the output of that exercise, not the input.
Delegation should buy something specific
There are three reasons I would readily add another agent: useful parallel work, a separate evidence-producing check, or a boundary that needs to be real.
Parallel work buys time or coverage.
Anthropic reported that its June 2025 research system, using an Opus 4 lead and Sonnet 4 workers, outperformed a single Opus 4 agent by 90.2% on its internal research evaluation. It particularly emphasized breadth-first investigations. The report also described much higher token use: about 15 times ordinary chat for multi-agent systems, versus about four times for agents. Those are comparisons with chat, not a claim that teams used 15 times the tokens of a single agent. [7]
That result is a serious counterexample to “teams are just obsolete scaffolding.” It is not an equal-budget proof that teams win everywhere.
For a broad investigation, I would happily send separate workers down distinct evidence trails and ask each for sources, findings, and unresolved contradictions. The lead can then concentrate on synthesis.
But I would not create a new agent just to run an independent command. A main agent can initiate parallel tool work too; LangChain explicitly distinguishes that from multi-agent coordination. [1]
Run the tests concurrently when appropriate. They do not need individual career paths.
A separate check buys a different opportunity to catch an error.
The valuable reviewer is not merely the one instructed to be grumpy. It is the one that receives the original acceptance criteria, inspects the actual artifact, and brings back something verifiable.
In the March harness report, Anthropic’s evaluator exercised applications through Playwright and returned concrete defects. The author also reported needing to tune the evaluator: a separate agent could still test superficially or excuse problems. Separation alone was not enough. [3]
For my own workflow design, I would give a reviewer room to form an initial judgment before seeing the builder’s defense of the work. I would ask for a failing test, a reproducible interaction, or a specific mismatch with the requirement.
That is an attempt to create evidential independence. A fresh context is not proof of statistically independent errors, particularly when both agents use the same model. Agreement is not a substitute for checking the artifact.
A real boundary buys control.
Suppose an exploratory worker can read untrusted material, while another component can approve a production action. I would keep the relevant permissions separate and enforce that separation in the runtime.
A skill saying “please be careful” is not an access-control mechanism. Conversely, another agent with the same unrestricted credentials has not created a meaningful boundary either.
The same reasoning applies to a worker with genuinely different tools or a separately evaluated specialist model. Keep it separate when the capability or constraint warrants separation—not simply because a diagram has an empty box.
Notice what is absent from these reasons: sounding like a company.
What this looks like on a real ticket
Take an illustrative TypeScript booking service. Two concurrent requests can both claim the last available place.
This is a hypothetical workflow, not a report of a production experiment.
A fixed-team approach could route the ticket through a planner, architect, database agent, API agent, tester, and reviewer. It could work. Before choosing it, I would want to know which of those handoffs solves a problem that one owner with the same knowledge cannot solve.
Here is the simpler candidate I would test.
First, establish the invariant. The owner reads the requirement and existing behavior, then records what must remain true: no oversubscription, no duplicate reservation from a retry, and a defined response for the request that loses the race. Existing authorization and API behavior remain constraints, not optional accessories.
That is the task contract. Every later decision and check must refer back to it.
Next, load the relevant capabilities. The owner uses the repository’s database-concurrency procedure, API conventions, and integration-test guidance. It traces the actual request path, examines how state changes are committed, and creates a reproducer before deciding on the fix.
The agent is not expected to guess the project’s conventions from its job title. Nor should it load the entire deployment manual unless the change touches deployment.
Delegate a bounded investigation only when useful. A worker might inspect other reservation entry points while the owner studies the main path. Give it a question, a code snapshot, read-only scope, and a required output: file locations, relevant behavior, and evidence of any path that can bypass the proposed protection.
Do not ask it to “be the architect.” Ask it something it can finish.
Keep integration with the owner. The owner decides how the findings affect the patch and updates the task record. If multiple workers must change code, specify their write boundaries and integration order; do not leave them negotiating ownership through overlapping edits.
Verify the resulting artifact. Run the reproducer, the relevant tests, and the agreed regression checks. A separate reviewer can then inspect the patch against the original invariant and exercise a less obvious scenario: retries, cancellation, another request path, or an unexpected failure between operations.
The useful output is the scenario and evidence, not a ceremonial approval.
Finally, the owner reports what changed, which checks ran, which passed, what remains uncertain, and whether the work was actually committed or merely described with tremendous confidence.
This design leaves a human or organization responsible for the release decision. Calling an agent the “owner” does not outsource accountability to software.
And yes: once the owner launches a worker or reviewer, this is technically a multi-agent system.
That is not a loophole. It is the point. I am arguing against a mandatory cast of permanent roles, not against invoking another model when there is a good reason.
The stable unit is the task and its evidence. The staffing is temporary.
Make the architectures compete, not the demos
To choose between these designs, I would run three candidates on the same representative tasks: a strong single agent with curated skills, a fixed specialist team, and an owner that can delegate selectively.
Give them equivalent access to the requirements, knowledge, tools, and checks. Let the team use the skills too. Otherwise the comparison is partly measuring whether one side was allowed to read the manual.
I would include sequential bug fixes, decomposable investigations, multi-file changes, and work that demands independent verification. Freeze the starting artifacts, record the model and skill versions, and repeat runs rather than choosing the most flattering transcript.
Two comparisons matter. Under an equal total spending cap, which system produces more accepted work? Under the same deadline, how much quality does each deliver, and what does it cost?
Those are different questions. More parallel work can be worth paying for when time matters. It should not quietly be presented as a free architectural improvement.
My scorecard would prioritize correctly completed tasks, regressions, missed requirements, time to an acceptable result, total cost, and human intervention. I would count the clarification, integration, and repair work too. A handoff that saves agent time by creating human cleanup has not disappeared from the bill.
Then remove components one at a time. Does removing the planner reduce quality? Does moving review to the end miss defects? Does replacing a permanent specialist with an on-demand skill change outcomes? Does adding one bounded worker actually shorten the critical path?
Anthropic’s broader guidance has long recommended starting with the simplest workable design and increasing complexity only when justified. It also distinguishes predefined workflows from agents that choose their own next actions. Some steps need a reliable function or a fixed check, not another autonomous participant. [8]
I would apply that discipline to skills as well. A long, stale procedure can deserve deletion just as much as a redundant agent.
Preference is not performance. Neither is a lively coordination transcript.
Keep the expertise. Make the headcount earn its place.
My default would be a capable owner with a small active context, reusable skills, durable task state, and checks that produce inspectable evidence.
I would add workers for genuinely separable work, reviewers when they improve verification, and separate components when capabilities or permissions demand it. I would retest those choices when the model, task mix, or tool environment changes.
That is not the claim that one agent can do everything. It is the refusal to assume that every useful capability needs its own employee.
If a second agent improves the result, keep it. If a sixth agent mainly explains what the other five are doing, check whether you have automated the work or merely reproduced the meeting.
Before adding another agent, name what it will contribute that the current system cannot supply as a skill, a tool, or a check.
If the answer is a job title, the org chart is doing more work than the architecture.
* * *
Notes and References
Evidence checked October 4, 2026. Benchmark percentages describe the cited evaluations, not guaranteed gains on other workloads. The recommended architecture and booking workflow are the author’s synthesis and proposal; no head-to-head production experiment is claimed here.
1. LangChain. “Multi-agent.” Documentation, accessed October 4, 2026. Distinguishes skills, subagents, handoffs, and their context/cost tradeoffs.
2. Anthropic. “Equipping agents for the real world with Agent Skills.” October 16, 2025; open-standard update December 18, 2025.
3. Prithvi Rajasekaran, Anthropic. “Harness design for long-running application development.” March 24, 2026. Engineering case studies; model and harness changes are not a controlled, equal-budget architecture trial.
4. Xiangyi Li et al. “SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks.” arXiv:2602.12670, version 4, June 14, 2026. Terminal-based benchmark; skill-count groups do not isolate the causal effect of adding another skill.
5. Anthropic. “Effective context engineering for AI agents.” September 29, 2025. Guidance on relevant context, compaction, and persistent notes.
6. Yubin Kim et al. “Towards a Science of Scaling Agent Systems.” arXiv:2512.08296, version 3, April 8, 2026. Benchmark-dependent findings; small coding subsets limit individual comparisons.
7. Anthropic. “How we built our multi-agent research system.” June 13, 2025. Internal evaluation using Claude 4 models; reported token multipliers use ordinary chat as the baseline.
8. Anthropic. “Building effective agents.” December 19, 2024. Cited for design principles, not as an inventory of current tools.